


What is an Autoregressive Language Model? What are its types and Usage ?
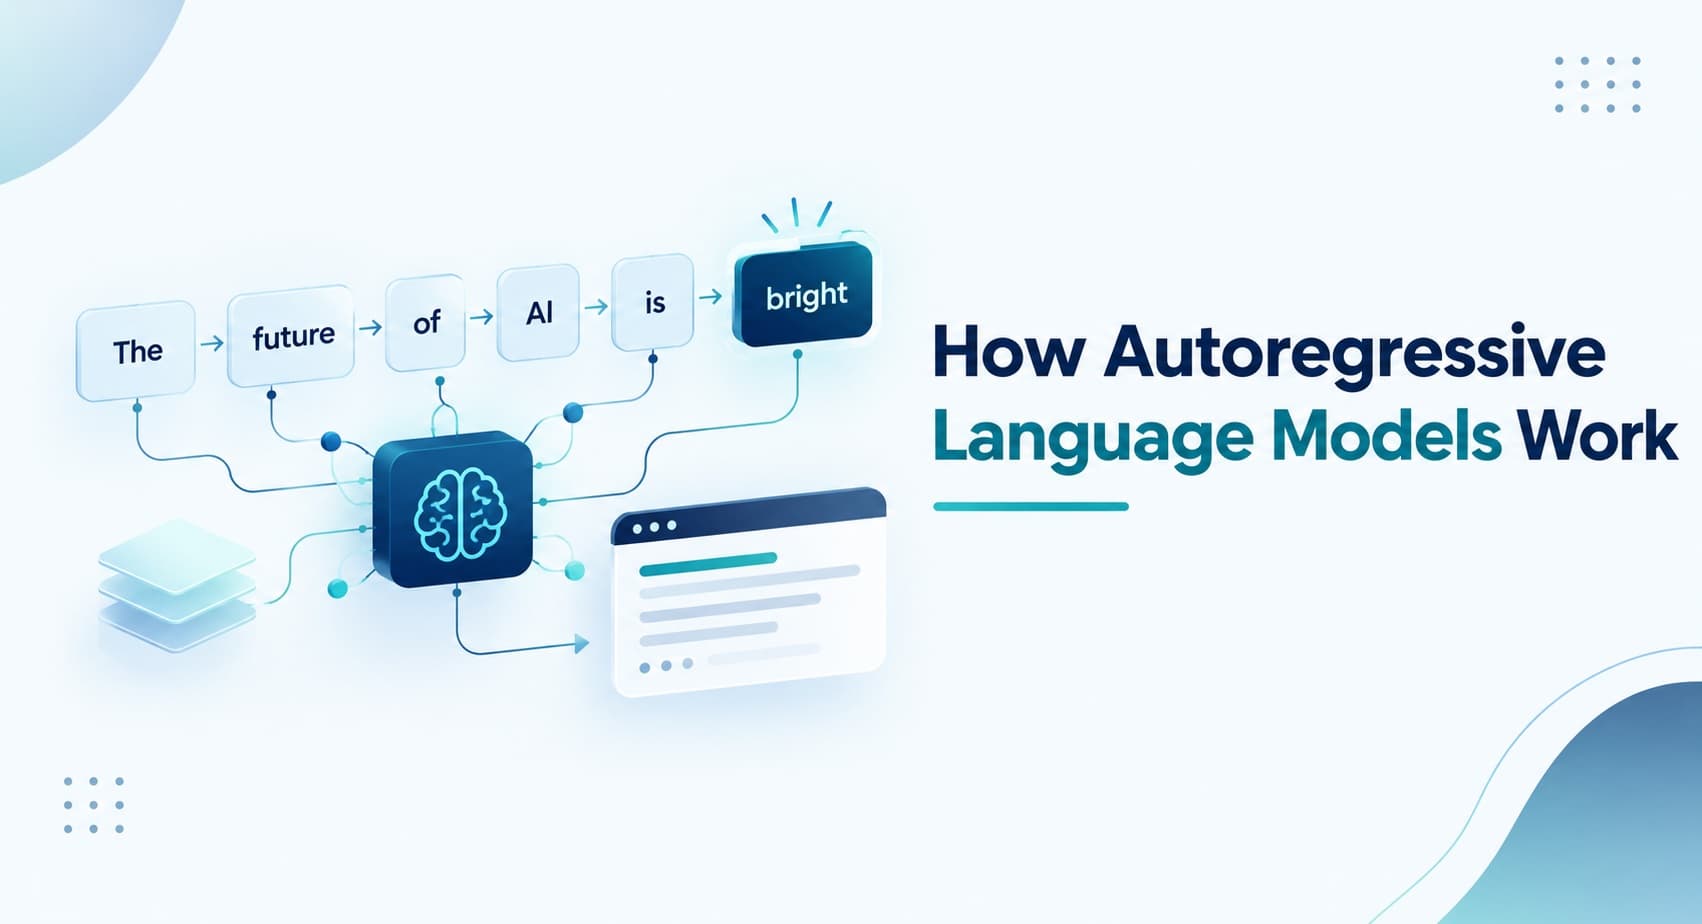


An autoregressive language model is an AI model that generates text one token at a time, predicting each new token from all the tokens that came before it. It’s the idea behind ChatGPT-style chatbots, the next-word suggestions on your phone keyboard, and most modern large language models (LLMs) and generative AI tools.
If you’ve come across the term in an article, a course or a job description and want a plain-English explanation, this guide covers it. You’ll learn how an autoregressive model in NLP works, the main types of autoregressive language models (RNN, LSTM, GRU, transformers and GPT), how they differ from masked models like BERT, where they’re used, and where they fall short.
What Is an Autoregressive Language Model?
An autoregressive language model is a type of neural network that generates text one token at a time. A token is a small unit of text, such as a word, part of a word or a punctuation mark. At each step, the model estimates which token is most likely to come next, given everything generated so far, then adds that token to the sequence and repeats. The same mechanism lets it complete a phrase, answer a question or draft a full document.
In research literature, this type of model is often called a causal language model, because each prediction depends only on earlier context and never on text that has not been produced yet. The name “autoregressive” describes the method: “auto” means self, and “regressive” refers to predicting a value from earlier values, so the model conditions every new output on its own previous outputs. This approach underlies most of today’s generative AI, including GPT, LLaMA, Claude and Gemini.
Autoregressive Model Example
Consider the prompt “I am going to the”. The model does not pick a single word at random. It scores every token in its vocabulary and assigns each one a probability of being the next token. The values below are illustrative, since real figures vary by model
Autoregressive Language Models in Numbers: Scale, Adoption and Trust
Autoregressive models have moved from research papers into everyday engineering work. Three figures show how far they have scaled, how widely they are used, and where confidence still lags.
Adoption is moving faster than confidence. Teams are adopting language-model tools quickly, yet nearly half of developers say they do not trust the output. The practical lesson of next-token prediction is that these models produce fluent text efficiently but need verification, grounding and testing built around them.
How Does an Autoregressive Model Work?
An autoregressive model works in two phases. It first learns patterns from large amounts of text, then uses those patterns to generate new text one token at a time.
Training on text data : The model is trained on large text collections. Its learning objective is simple: given a sequence of tokens, predict the one that follows. Repeated across billions of examples, this teaches the model grammar, facts, style and common reasoning patterns.
Tokenization : Text is split into tokens (words or word pieces) and converted into numbers, which the model can process. A rare word such as “unbelievable” may be split into several pieces, while a common word is usually a single token. Each token is then mapped to a vector, a form known as a token embedding.
Predicting the next token : The model reads the tokens so far and produces a probability for every token in its vocabulary.
Selecting a token: A decoding method picks one token from those probabilities. Greedy decoding always takes the most likely token. Sampling methods such as temperature, top-k and top-p introduce controlled variety, which is why outputs differ between runs.
Appending and repeating: The chosen token is added to the sequence, and steps 3 and 4 run again. The loop ends when the model emits an end-of-sequence token or reaches a length limit.
Training and generation behave differently. During training, the model is shown the correct text and learns to predict each next token at every position at once, so the work can run in parallel. During generation, there is no finished text to read, so each token must wait for the one before it. This is why training scales well, while long outputs take proportionally longer to generate.
For example, given the prompt “Once upon a time,” the model might produce “there,” then “was,” then “a,” and continue until a story takes shape, one token at a time.
Quick Code Example
The snippet below uses the open-source Hugging Face transformers library with GPT-2, a classic autoregressive model, to continue that same prompt. It’s one of several Python AI libraries commonly used for language tasks. Install the dependencies first:
pip install transformers torchfrom transformers import pipeline
generator = pipeline("text-generation", model="gpt2")
result = generator("Once upon a time", max_new_tokens=30)
print(result[0]["generated_text"])Illustrative output (yours will differ): “Once upon a time, there was a small village at the edge of a forest, where the people...”
The output varies from run to run because the model samples from its probability distribution. For repeatable results, add do_sample=False to the call, which switches to greedy decoding. The first run also downloads the model, so allow a short wait.
How Code B Can Help You Build with Language Models
Understanding how autoregressive models work is the first step. The harder part is turning them into a product that is accurate, fast enough for real users and affordable to run. That means choosing the right model size, grounding outputs in your own data, controlling latency and token costs, and keeping the system reliable after launch.
Code B’s AI team works on these decisions with product teams, from scoping a first use case to shipping and maintaining it. This includes assistants and chatbots, content and document workflows, and integrating language models into existing applications and data systems.
Autoregressive vs Masked Language Models: What’s the Difference?
Autoregressive and masked models are trained for different jobs. An autoregressive model predicts the next token from the tokens before it, while a masked model recovers hidden tokens using the words on both sides.
Autoregressive models are the better choice when you need to generate new text. Masked models are stronger when you need to understand or classify existing text.
A third approach, diffusion or non-autoregressive models, generates a whole sequence by refining it over several passes instead of one token at a time. It is an active research area, but autoregressive models still dominate production text generation.
Where Are Autoregressive Language Models Used?
Autoregressive models power most of the systems that produce text on demand, from the support chatbot on a company website to the code suggestions inside a developer’s editor. In business, they show up in customer-facing assistants, in internal workflows such as drafting and summarizing documents, and in developer tools. Beyond language, the same approach is applied to audio, images and other sequential data. The applications below show where these models are used most often today and what each one does in practice.
Text Generation and Summarization
The most direct use is generating text from a prompt: drafting articles, product descriptions, emails and reports, or continuing a passage in a given style. The same mechanism handles summarization, where the model reads a long document and writes a shorter version one token at a time. Businesses use this to speed up content production, condense research, and turn long records into briefs.
Chatbots and Virtual Assistants
Modern AI assistants generate each reply token by token, conditioned on the conversation so far. Because the full dialogue stays in context, responses can follow earlier questions, keep a consistent tone and handle follow-ups. This is the basis of customer support bots, internal knowledge assistants and general-purpose tools such as ChatGPT and Claude.
Language Translation
Many neural translation systems generate the translated sentence one token at a time, with each word informed by the source sentence and the words already produced. Large language models are also widely used for translation, particularly where tone and context matter more than word-for-word accuracy.
Code Generation
Code is a sequence of tokens with strict structure, which suits next-token prediction well. Tools such as GitHub Copilot use autoregressive models to suggest and complete code, write functions from a comment, and explain unfamiliar snippets. Output should still be reviewed and tested, since the model predicts plausible code and does not verify that it works.
Beyond Text
The same approach applies to any data that forms a sequence. Examples include audio generation (WaveNet), image generation (PixelCNN), music composition and time-series forecasting. Speech recognition systems such as Whisper also use an autoregressive decoder to write out the transcript token by token.
Why Are Autoregressive Language Models Important?
Autoregressive models matter because one simple training objective, predicting the next token, produces a system that can be applied to a very wide range of work. Three qualities explain most of that value.
- Versatility : A single model can write, summarize, translate, answer questions and generate code, because all of these tasks can be framed as continuing a sequence. This lets teams build many features on one foundation instead of maintaining a separate model for each task.
- Adaptability : A pre-trained model can be tailored to a specific domain or style without starting over. Techniques such as prompting, fine-tuning and LoRA fine-tuning adjust its behavior using far less data and compute than training from scratch, which makes domain-specific assistants practical for smaller teams.
- Scalability : Transformer-based autoregressive models keep improving as data, model size and compute grow, which is why they sit behind most of today’s large language models. Because training runs in parallel, this scaling has been practical in a way it was not for earlier recurrent models.
For businesses, the result is a single technology that supports customer support, content operations, software development and analytics, and that can be refined as needs change.
What Are the Limitations of Autoregressive Language Models?
Autoregressive models are powerful, but the same mechanism that makes them fluent also creates trade-offs. Five limitations are worth understanding before you build on them.
Slow Inference
Because tokens are generated one at a time, and each depends on the one before it, output cannot be produced all at once. Generation time therefore grows with the length of the response. A short answer returns quickly, while a long report or a detailed code file takes noticeably longer, which affects latency in real-time products such as chat interfaces and voice assistants.
Teams reduce this with smaller models, response length limits and caching of earlier computation, but the underlying sequential behavior remains.
Error Accumulation
Every token the model produces becomes input for the next prediction. If an early token is wrong, off-topic or poorly chosen, the model treats it as fact and builds on it, so the mistake can carry forward and shape everything that follows.
This is most visible in long outputs, where a small slip in the opening lines can lead the whole response in the wrong direction.
Hallucinations
An autoregressive model is trained to predict likely text, not to verify facts. When it lacks reliable knowledge on a topic, it still produces fluent, confident-sounding output, which can include invented details, figures or sources. For this reason, any output that informs a decision, a customer or a published page should be checked against a trusted source.
Grounding the model in retrieved, verified data and validating its output reduce the risk, but they do not remove it.
No Look-Ahead During Generation
The model writes in a single left-to-right pass. It cannot go back and revise an earlier word in light of what it writes later, and it cannot see the end of a response before producing the beginning. Planning the structure of a long answer in advance is therefore harder than it is for approaches that see the whole text at once.
In practice, this is why prompts that ask for an outline or step-by-step reasoning first often give more coherent results.
High Compute Cost
Training large models requires significant GPU resources, and serving them is not free either. Cost scales with the number of tokens processed and generated, so heavy usage, long prompts and long responses all raise the bill. Managing this in production is a discipline of its own, covered in our guide to LLMOps.
Conclusion
An autoregressive language model predicts one token at a time from everything that came before it. That simple idea drives GPT, LLaMA, Claude, and most other modern LLMs. Understanding how these models work, where they excel, and where they fall short helps you choose the right approach for your AI project.
Building an AI-powered product? Explore the top AI development tools and platforms, see how generative AI is used in e-commerce, or hire AI/ML developers to build your solution.
Frequently Asked Questions

 WhatsApp
 Call Us
 Mail Us