




What Is CRUD in APIs and Databases?

CRUD defines the four core actions used to manage data in any application: Create, Read, Update, and Delete. These operations control how data is stored, accessed, modified, and removed within a system, forming the foundation of database interactions and modern backend development practices.
What Does CRUD Stand For?
CRUD stands for Create, Read, Update, and Delete. Each operation represents a specific way data is handled within an application. Create adds new entries, Read retrieves stored data, Update modifies existing values, and Delete removes data from the system.
How CRUD Operations Work in Databases
In databases, CRUD operations are applied to structured data stored in tables. Each table contains records, and queries are used to interact with those records based on the required operation.
Create inserts new records into a table, Read retrieves data through queries, Update modifies specific fields within existing records, and Delete removes records entirely. These operations are executed at the database level before any API processes the request.
Understanding this layer is important, since APIs rely on these operations to handle data behind the scenes.
Real-World Example of CRUD Operations

A user management system helps illustrate how CRUD operations work in practice. When a new user signs up, their information is stored in the database as a new record.
To display user details, the system retrieves that data based on a unique identifier such as a user ID. If the user updates their email or profile information, the existing record is modified to reflect those changes.
When a user decides to delete their account, the system removes that record from the database. These steps show how CRUD operations manage data throughout its lifecycle within an application.


What Is a REST API and How Does It Work?

A REST API enables applications to communicate over HTTP through defined endpoints. Instead of accessing a database directly, clients send requests to an API, which processes the request and returns structured responses, typically in JSON format. Each endpoint represents a resource and defines how it can be accessed.
REST Architecture Explained
REST, or Representational State Transfer, defines a set of rules for structuring APIs. It focuses on consistent communication between client and server, ensuring that requests and responses follow predictable patterns. To maintain this consistency, REST relies on a few core principles that guide how requests are handled.
One of the key principles is statelessness, where each request contains all the information needed to process it. The server does not store previous request data, which keeps interactions independent and easier to manage. This stateless approach directly influences how APIs are structured and how resources are accessed.
APIs are designed around resources, accessed through URLs such as /users or /orders, which keeps endpoints structured and easier to understand. This resource-based design, combined with stateless communication, forms the foundation of how REST APIs operate in real-world applications.
HTTP Methods Used in REST APIs
REST APIs use standard HTTP methods to define how resources are accessed and modified. Each method corresponds to a specific type of operation performed on the data.
GET retrieves data from the server, POST creates new data, PUT replaces an existing resource, PATCH updates specific fields, and DELETE removes a resource.
This structure allows developers to interact with APIs in a consistent way, especially when validating behavior through API testing practices.
Common REST API Endpoint Examples

REST APIs use endpoints to represent resources and define available operations. Each endpoint follows a predictable pattern, making it easier to understand how the API behaves.
A GET request to /users retrieves all users, while a POST request to the same endpoint creates a new user. Accessing /users/:id allows interaction with a specific record.
Updating that record is handled using PATCH, and removing it is done through DELETE. This structure keeps APIs consistent and easier to integrate across different systems.
How REST APIs Use CRUD Operations.
REST APIs use standard HTTP methods to perform data operations that follow the CRUD model. Instead of interacting with a database directly, clients send requests to an API, which processes the request and returns structured responses, typically in JSON format.
This mapping creates a consistent way to handle data across applications. It allows developers to design APIs where actions are predictable, making it easier to build, test, and integrate systems.
Mapping CRUD Operations to HTTP Methods
CRUD operations are translated into HTTP methods when exposed through a REST API. Each method represents a specific action performed on a resource, which keeps the API structure consistent.
Create operations are handled using POST requests, while read operations use GET to retrieve data. Update operations are mapped to PUT or PATCH depending on how the data is modified, and delete operations use DELETE to remove a resource.
This mapping ensures that anyone working with the API can understand its behavior based on the request method alone, without needing to know the internal implementation, as most modern software frameworks follow this structured approach.
PUT vs PATCH Difference
PUT and PATCH are both used for updating data, but they serve different purposes. PUT replaces the entire resource, meaning all fields are updated, even if only one value changes.
PATCH, on the other hand, updates only specific fields within a resource. This makes it more efficient when only partial changes are required, such as updating a user’s email without affecting other data.
Choosing between PUT and PATCH depends on how the API is designed. PUT is used when a complete update is expected, while PATCH is preferred for smaller, targeted changes.
Why Does This Mapping Matter in Real Systems?
Mapping CRUD operations to HTTP methods creates a clear and predictable structure for APIs. Each request follows a defined pattern, which reduces confusion and makes systems easier to work with as they grow.
In distributed backend systems, multiple services rely on APIs to communicate, making consistency in how requests are handled essential for reliable data exchange.
This structure ensures that services can exchange data without depending on each other’s internal logic, which helps maintain stability as systems become more complex.
Key Differences Between CRUD and REST APIs
CRUD and REST are often used together in API development, but they serve different roles. CRUD defines how data is handled within a system, while REST defines how that data is accessed and transferred over a network.
Understanding this distinction helps clarify how backend systems are structured and how APIs interact with data.
How CRUD and REST Work at Different Layers?
The difference between CRUD and REST comes down to their role in a system. CRUD operates at the data level, focusing on how records are created, retrieved, updated, and deleted within a database.
REST operates at the communication level, defining how clients interact with those operations through HTTP requests. It provides a structured way to access resources using endpoints and standard methods.
Another key distinction is how the state is handled. CRUD operations depend on the current state of stored data, while REST follows a stateless approach where each request is processed independently.
REST also standardizes how data is exchanged between systems using HTTP methods and formats such as JSON, which keeps communication consistent across different applications.
Comparison Table Between CRUD and REST API
CRUD and REST APIs differ in how they handle data and communication. The table below highlights the key differences across their role, scopes, and usage in a system.
This comparison shows that CRUD is focused on how data is handled within a system, while a REST API defines how that data is accessed and shared across applications.
Why CRUD and REST APIs are Often Confused
CRUD and REST are closely related in practice, which often leads to confusion. When building APIs, REST is used to expose endpoints, and those endpoints internally perform CRUD operations on the database.
For example, a POST request creates a new record, while a GET request retrieves data. This direct mapping makes it seem like CRUD and REST are interchangeable, even though they operate at different layers.
The confusion comes from this overlap, where both are used together in implementation but serve separate purposes within the system.
How Do REST APIs and CRUD Work in Real-World Examples?
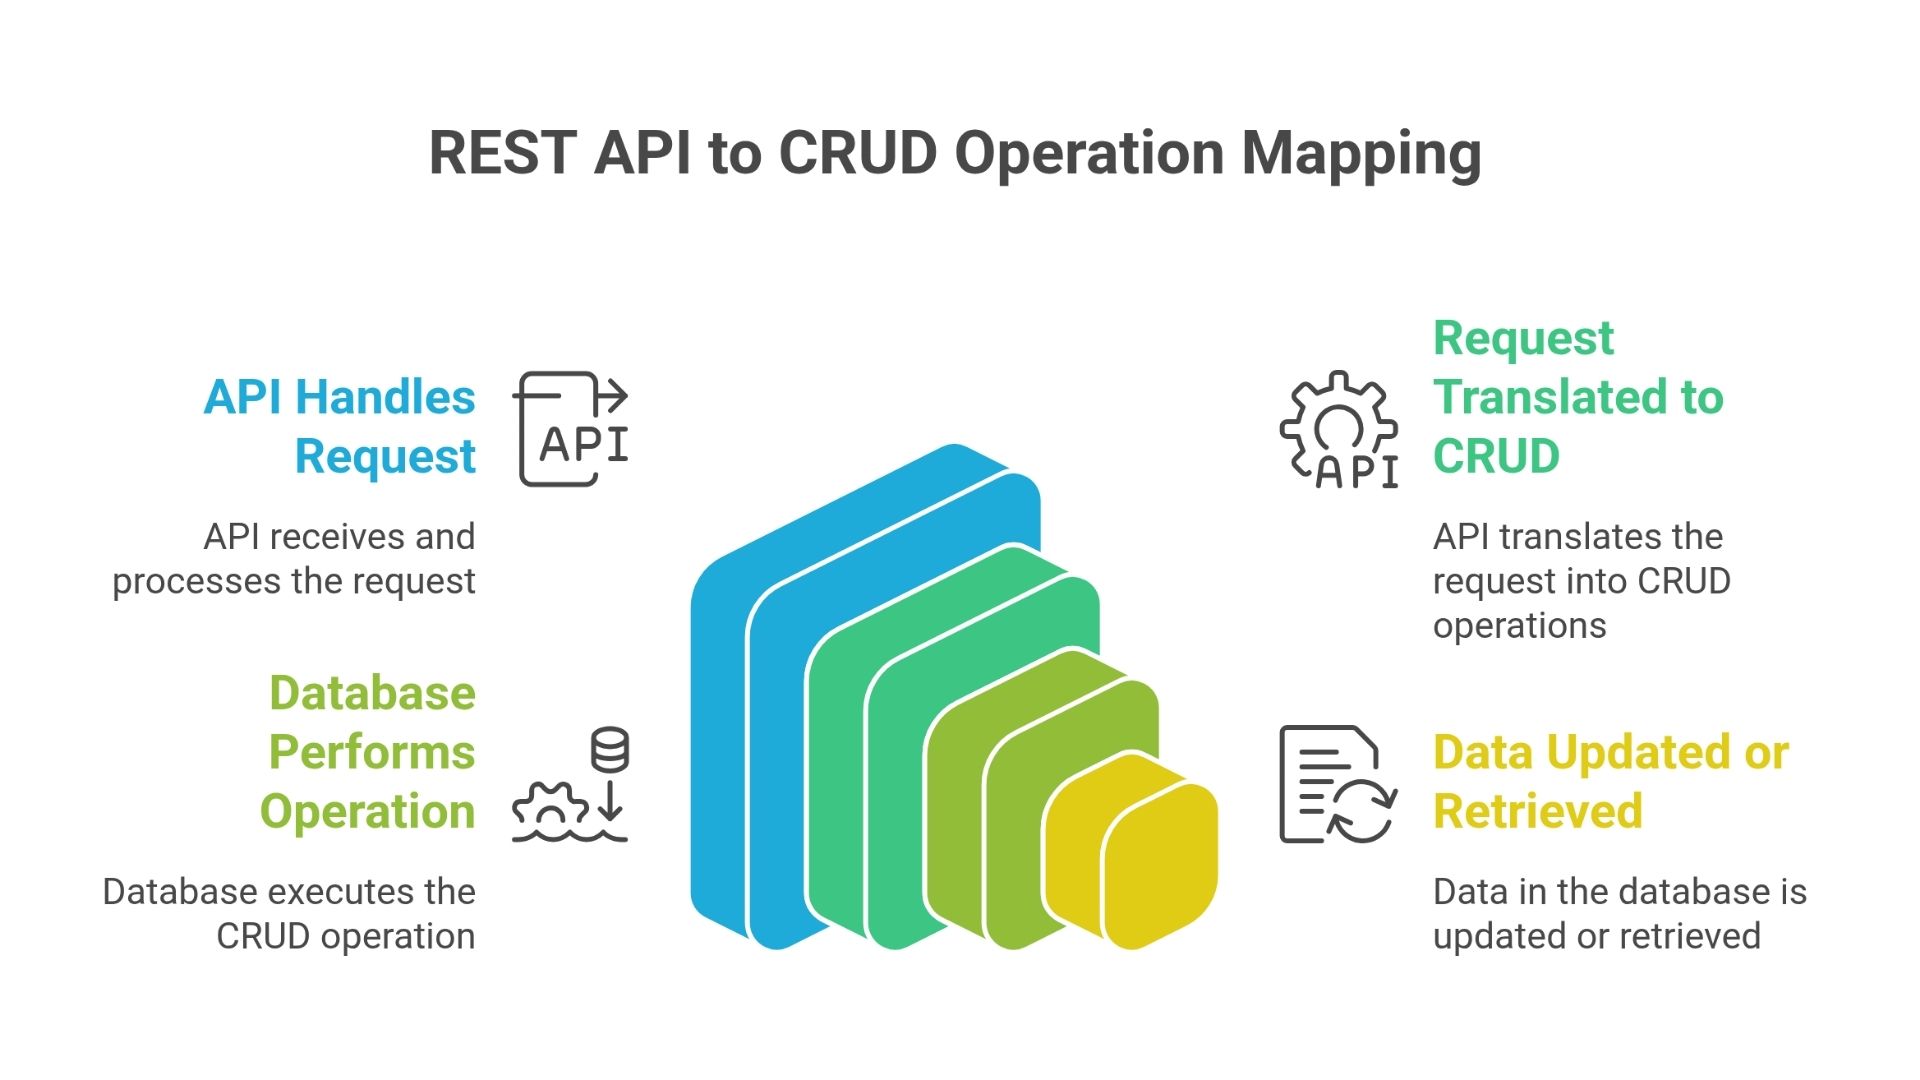
The relationship between CRUD operations and REST APIs becomes clearer when applied to real systems. Most applications follow a consistent pattern where APIs handle requests, and database operations manage how data is stored and updated.
The examples below show how this mapping works in practice across different levels of application complexity.
Managing Data in Task-Based APIs
Simple applications such as task management tools or small e-commerce systems show the most direct relationship between REST and CRUD. When a client sends a GET request to retrieve items, the system performs a read operation, while a POST request creates a new record such as a task or product.
Creating a new task involves a POST request, which stores the data as a new record. Updating a task uses PUT or PATCH depending on whether the entire task or specific fields are modified, while DELETE removes the task from the database.
This type of setup is commonly used in applications that manage structured data, where each API request directly maps to a database operation.
Working with Products and Users in Resource-Based APIs
In larger applications such as e-commerce platforms and food delivery services, APIs are structured around resources like users, products, and orders. Each endpoint represents a resource, and HTTP methods define how that data is accessed or modified.
Fetching a product or order uses GET, adding a new entry uses POST, and updating or deleting data follows PUT, PATCH, or DELETE. These requests are handled by the API layer and translated into CRUD operations at the database level.
This structure keeps APIs predictable and easier to work with when different parts of an application interact with shared data and rely on consistent request handling. In complex systems, request routing and service coordination are handled through API gateways that sit between clients and services.
Handling Transactions and Data Flow in Complex Systems
In systems that handle transactions, such as booking platforms or order-based applications, CRUD operations are performed continuously as users interact with the system.
Creating a booking stores a new record, retrieving details reads existing data, updating availability modifies records, and canceling removes or updates entries.
These operations are triggered through API requests, which follow REST principles to ensure consistent communication between the client and server.
This pattern appears in most real-world applications where data changes frequently and needs to stay synchronized across the system.
When Should You Use CRUD or REST API?
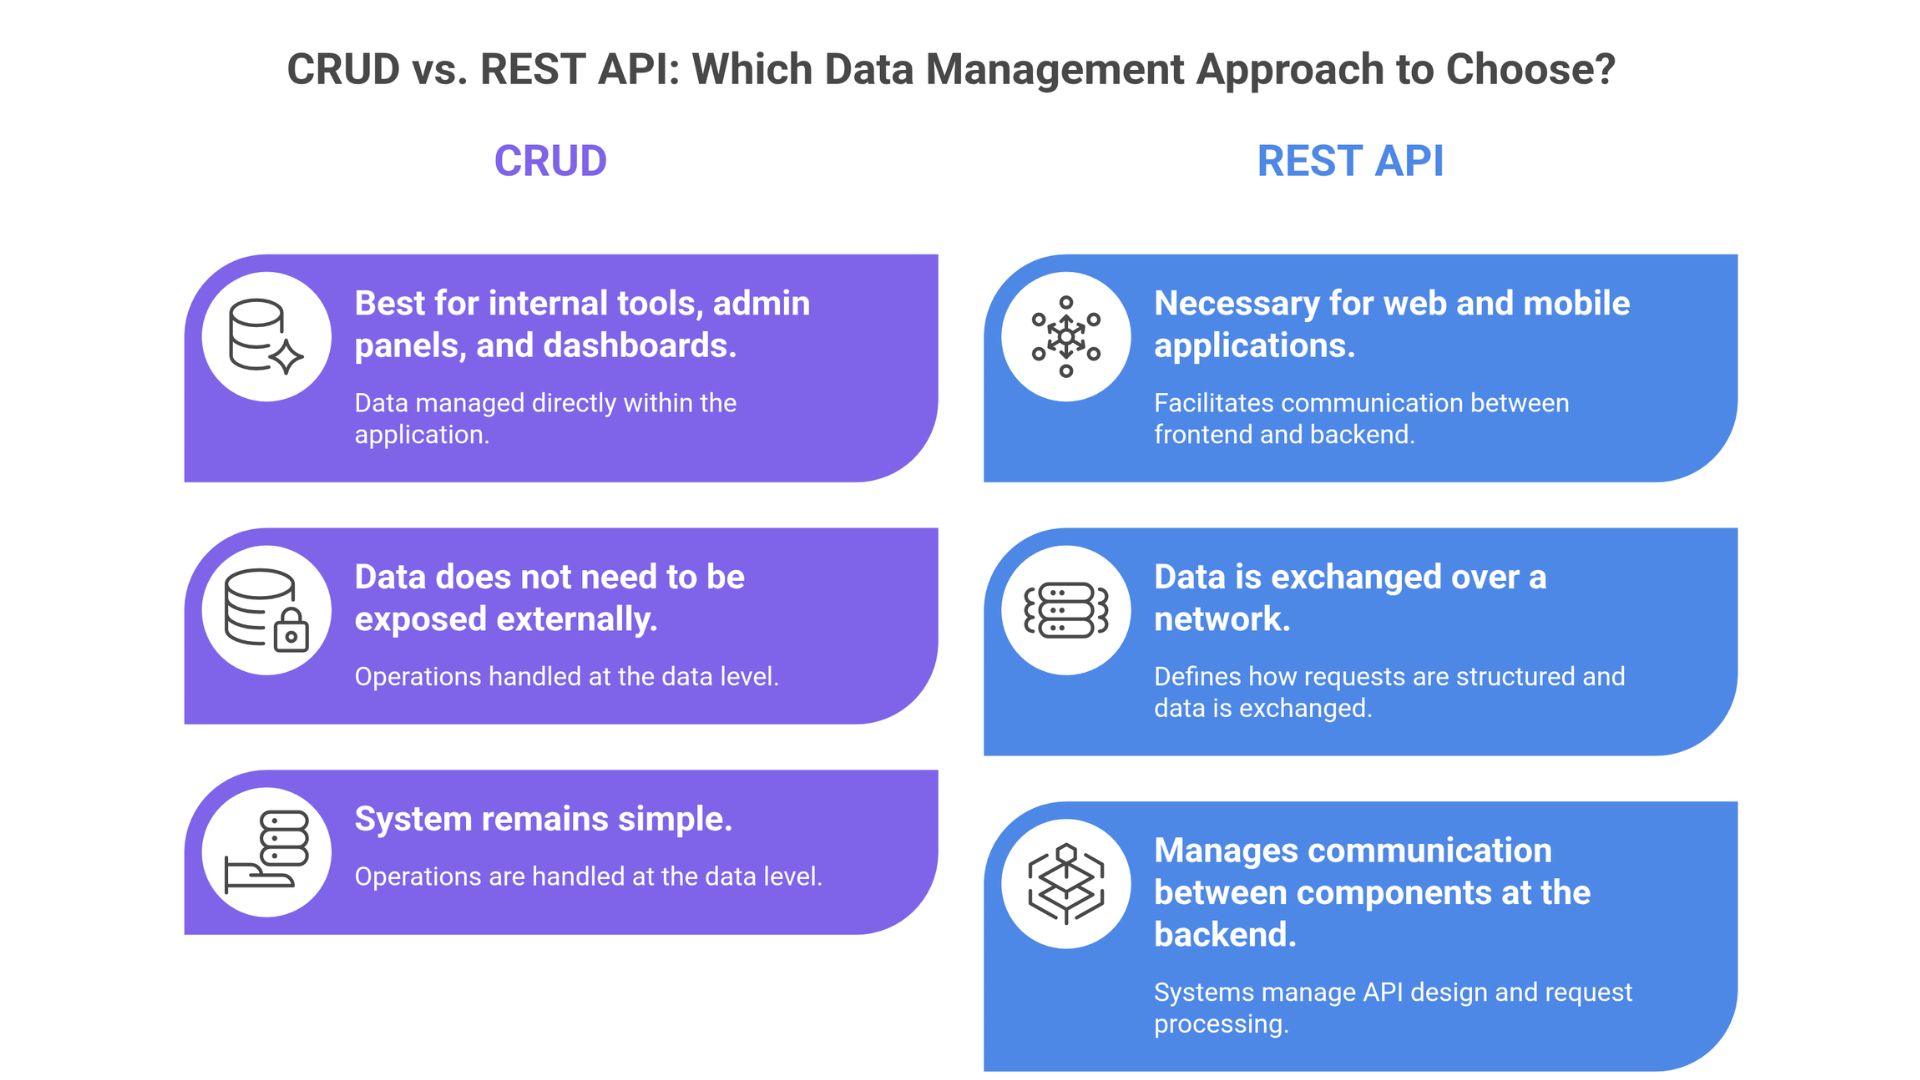
Choosing between CRUD and REST depends on how your application is structured and how data flows within the system. Instead of treating them as alternatives, it is more useful to understand where each one fits.
When CRUD Is Enough?
CRUD works best in systems where data is managed directly within the application and does not need to be exposed externally. This includes internal tools, admin panels, and dashboards where users interact with the database through a controlled interface.
In these cases, operations are handled at the data level without defining endpoints or managing HTTP requests. The system remains simple because all interactions stay within a single environment.
When Does REST API Become Necessary?
REST is required when your application needs to communicate across different layers, such as between a frontend and backend or across multiple services. It defines how requests are structured and how data is exchanged over a network.
This is commonly seen in web and mobile applications, where the client depends on APIs to retrieve and update data. Systems built on this architecture manage API design, request processing, and communication between components at the backend.
When Are CRUD and REST Used Together?
In most real-world applications, CRUD and REST are not used separately. REST APIs handle how data is requested and transferred, while CRUD operations define how that data is stored and modified within the database.
This separation allows systems to stay organized as they grow. APIs manage communication between components, while the data layer focuses on maintaining consistency and handling operations efficiently.

Common Mistakes When Using CRUD and REST APIs
Confusion between CRUD operations and REST APIs often leads to implementation mistakes that affect how systems are designed and how data is handled. These issues usually appear when the roles of data operations and API architecture are not clearly separated.
Treating CRUD as an API Design Approach
A common misunderstanding is assuming that CRUD dictates how an API should be structured. CRUD only describes operations on data create, read, update, delete but it does not define how endpoints should be organized or exposed.
When developers design APIs directly around CRUD without considering REST principles, they often end up exposing database-like endpoints. This leads to routes that mirror internal logic rather than representing meaningful resources, making the API harder to understand from a client perspective.
Over time, this approach creates rigidity. As business logic evolves, APIs built this way become difficult to extend because they are tightly aligned with database operations instead of user-facing use cases.
Incorrect Use of HTTP Methods
Misusing HTTP methods is one of the fastest ways to break API consistency. For example, using GET requests to modify data or POST requests to retrieve information goes against standard HTTP semantics.
Each method has a clearly defined purpose. GET should only retrieve data, POST should create new resources, PUT and PATCH should update data, and DELETE should remove it. When these conventions are ignored, the API becomes unpredictable for clients.
This inconsistency also affects caching, debugging, and integration. Tools and systems rely on standard HTTP behavior, so incorrect usage can introduce subtle bugs and make the API harder to test and maintain.
Poor Resource Naming in Endpoints
Endpoints should represent resources, not actions. Using routes like /getUsers or /deleteUser reflects procedural thinking rather than REST design.
A resource-based approach such as /users combined with HTTP methods keeps the API clean and intuitive. The method defines the action, while the endpoint defines the resource. This separation improves clarity and reduces redundancy in route definitions.
As APIs grow, inconsistent naming creates confusion across teams. Clear and standardized resource naming ensures that developers can navigate and use the API without needing constant reference to documentation.
Ignoring Stateless Communication
REST APIs are designed to be stateless, meaning each request should contain all the information required to process it. The server should not rely on previous requests or stored session data.
When state is stored on the server, it introduces hidden dependencies between requests. This makes debugging harder because issues may depend on prior interactions that are not immediately visible.
Stateless design improves scalability and reliability. Since each request is independent, it can be handled by any server instance, making it easier to distribute load and maintain consistent behavior across the system.
Tight Coupling Between API and Database
Another frequent mistake is exposing database structure directly through the API. This creates a strong dependency between how data is stored and how it is accessed.
When the database schema changes, APIs built this way often break or require significant rework. This slows down development and increases the risk of introducing bugs during updates.
A better approach is to treat the API as an abstraction layer. The API should represent business logic and use cases, not internal database design. This allows the backend to evolve without affecting how clients interact with the system.
Inconsistent Response Handling
Inconsistent responses make APIs difficult to work with. Returning different formats for similar operations or using incorrect HTTP status codes creates confusion for clients.
For example, always returning 200 OK even when an error occurs forces clients to manually inspect responses instead of relying on standard status codes. This increases complexity and makes error handling less reliable.
A well-designed API uses consistent response structures and appropriate status codes. This helps clients quickly understand the outcome of a request and handle success or failure cases efficiently.
What Are the Best Practices for REST APIs with CRUD Operations
Designing REST APIs around CRUD operations requires a clear structure in how requests are handled and how data is exposed. When endpoints follow consistent patterns, it becomes easier to work with the API, debug issues, and extend functionality without breaking existing behavior.
These practices focus on keeping request handling predictable, improving clarity for developers, and reducing errors as the application grows.
Use HTTP Methods Correctly
Each HTTP method should map to a specific operation. GET is used to retrieve data, POST to create records, PUT to replace existing data, PATCH to update selected fields, and DELETE to remove resources.
When methods are used correctly, clients can understand how an endpoint behaves without relying on additional explanation. This makes integration smoother and reduces the chances of incorrect implementation on the client side.
Using the wrong method, such as updating data with GET or retrieving data with POST, leads to confusion and inconsistent behavior. Following the standard method usage keeps APIs easier to test and maintain.
Keeping APIs Stateless
Every request should include all the information required for processing. The server should not depend on previous interactions or stored session data.
Handling each request independently simplifies debugging and prevents issues from spreading across multiple requests. It also ensures that failures remain isolated and easier to track.
In systems where multiple services interact, stateless communication helps maintain consistency. Each request follows the same structure, making the API easier to reason about and extend.
Using clear resource naming
Endpoints should represent resources instead of actions. Using /users instead of /getUsers keeps the API aligned with REST principles and improves readability.
Clear naming helps developers understand what each endpoint does without needing to inspect the implementation. It also reduces confusion when different parts of the system interact with the same API.
As applications expand across services, consistent resource naming helps maintain structure. In distributed systems, this consistency ensures that APIs remain predictable across different services.
Validate Inputs and Handle Errors Properly
All incoming data should be validated before processing. This prevents invalid or unexpected input from affecting the system and ensures that operations behave as intended.
Error responses should follow a consistent format and use appropriate HTTP status codes. This allows clients to identify issues quickly and respond accordingly.
Clear validation rules and structured error handling reduce debugging time and help maintain stable behavior as the application evolves.
Conclusion
CRUD and REST are often discussed together, but they solve different problems. CRUD focuses on how data is created, retrieved, updated, and deleted, while REST defines how that data is accessed and communicated through APIs.
Understanding this distinction helps avoid common implementation mistakes. Treating CRUD as an API design approach or misusing HTTP methods can lead to unclear and difficult-to-maintain systems.
In real applications, both are used together. REST handles how requests are structured and sent between systems, while CRUD manages how data is processed within the backend. Keeping these roles separate leads to cleaner APIs and more predictable behavior.
Frequently Asked Questions (FAQs)

 WhatsApp
 Call Us
 Mail Us