


How Do Small Language Models (SLMs) Work? A Full Guide


Large language models get most of the attention, but they aren't always the right tool. They're expensive to run, slow to respond, and often need to send your data to a third-party cloud. For many real-world tasks, that's overkill.
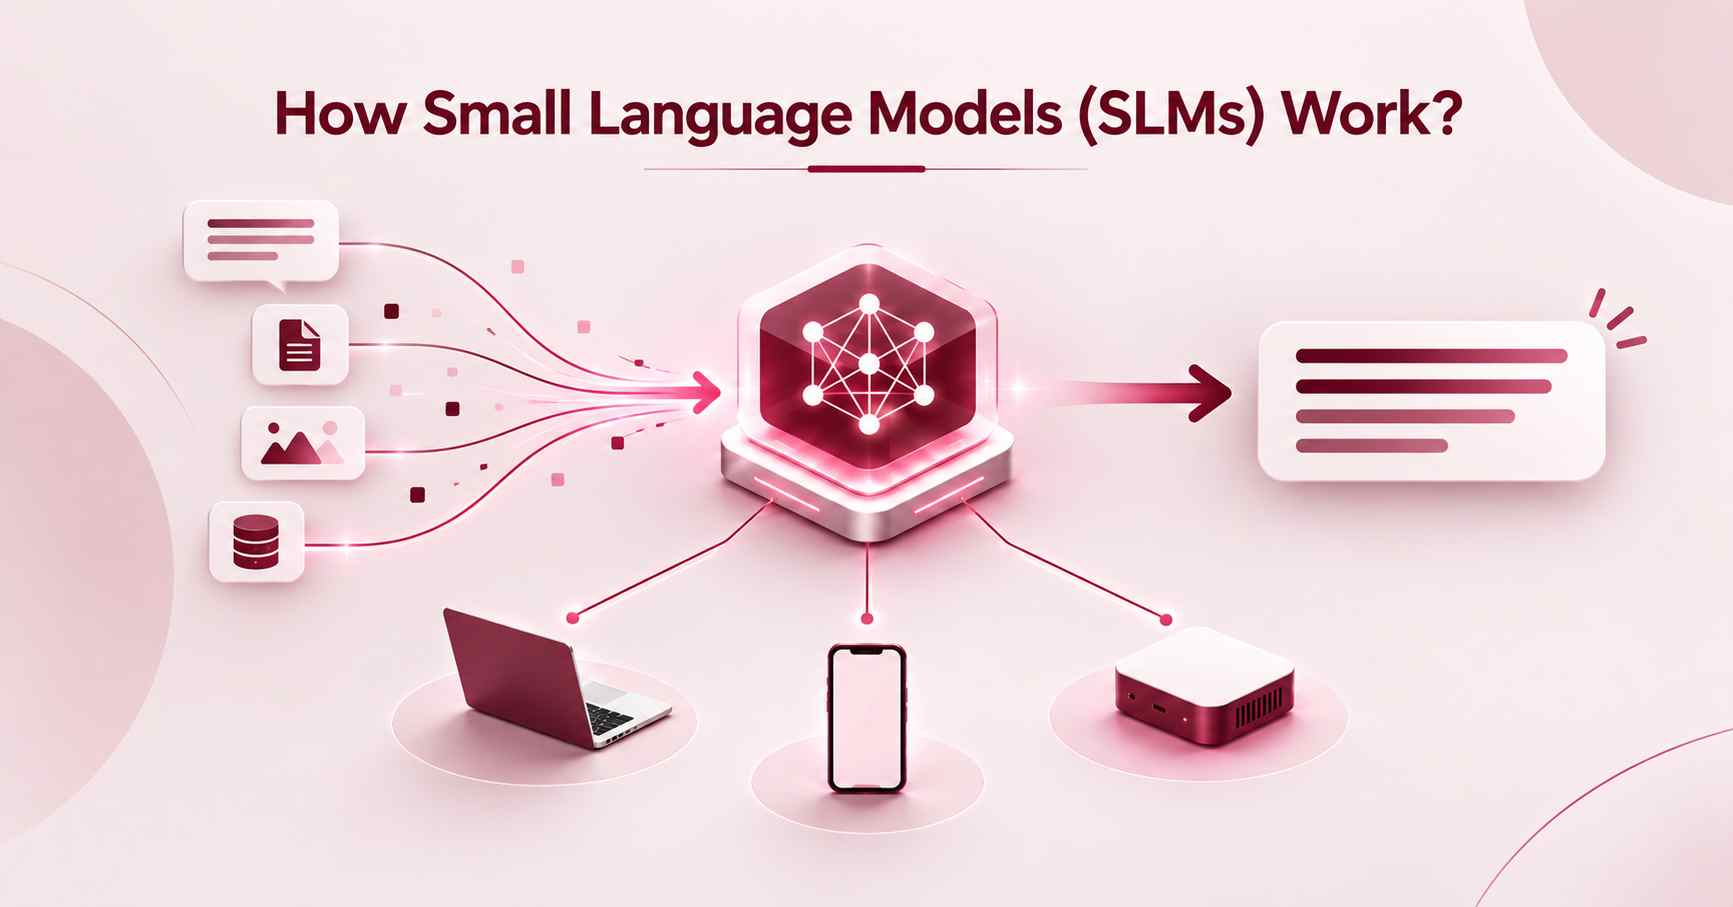
That's where small language models (SLMs) come in. SLMs are compact AI models, typically ranging from a few hundred million to around 10 billion parameters. They're built to handle focused tasks well while running faster, costing less, and working on everyday hardware like laptops, phones, and edge devices.
As businesses move from AI experiments to production, SLMs are becoming a practical choice for chatbots, on-device assistants, private enterprise tools, and AI agents.
What Are Small Language Models (SLMs)?
Small Language Models (SLMs) are compact artificial intelligence models designed to understand, process, and generate human language. Like Large Language Models (LLMs), they can work with text and perform tasks such as answering questions, summarising documents, classifying content, extracting information, and generating responses. The key difference is that SLMs are built with fewer parameters and generally require less computing power, memory, and storage.
There is no universally fixed parameter count that defines an SLM. In practice, a model is considered “small” when it is significantly lighter than the large models typically used for broad, general-purpose AI applications. Their smaller architecture allows them to be deployed in environments where running a large model may be expensive, slow, or impractical.
How Do Small Language Models (SLMs) Work?
Small Language Models work on the same fundamental principle as larger language models: they learn patterns in language from training data and use those learned patterns to predict and generate text. The difference is that SLMs are designed to achieve useful performance with a smaller computational footprint.
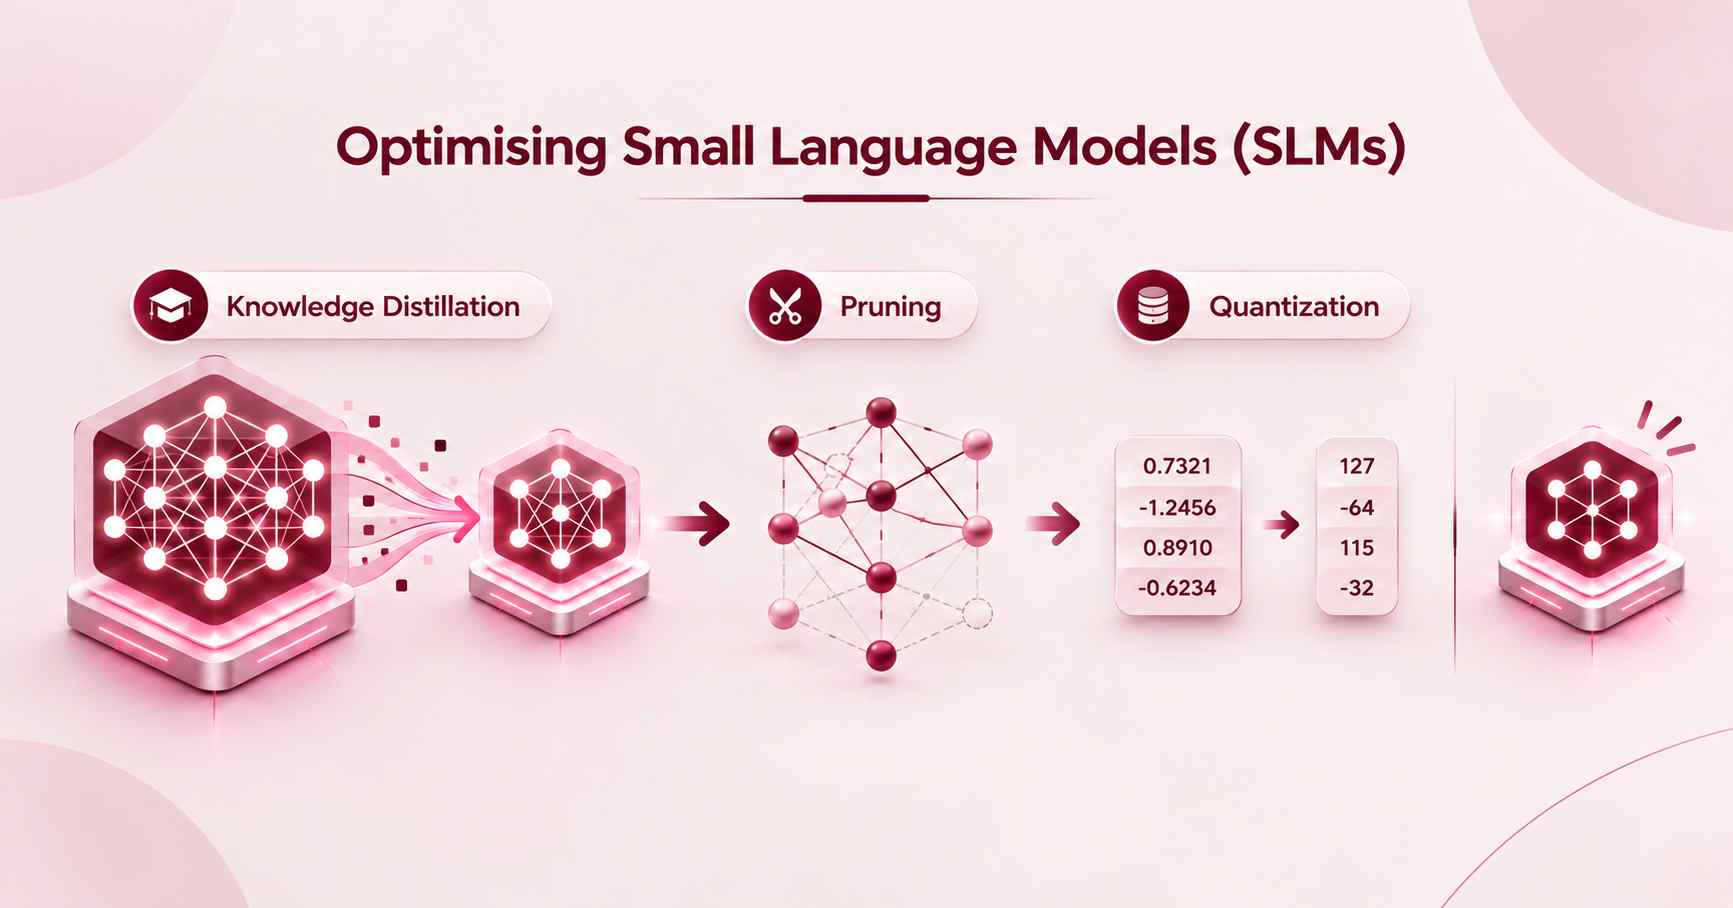
A major part of building an SLM is reducing the size and computational requirements of an existing model without losing too much of its useful capability. Three commonly used techniques for this are knowledge distillation, quantization, and pruning.
1. Knowledge Distillation
Knowledge distillation is a technique in which a smaller student model learns from a larger, more capable teacher model. Instead of training the smaller model entirely from scratch, the teacher provides additional information about how it understands and responds to different inputs.
The teacher model generates outputs, probability distributions, or other useful signals from which the student learns. This allows the smaller model to imitate many of the behaviours and patterns learned by the larger model.
For example, a large language model may be capable of understanding a wide range of customer queries. A smaller model can be trained using the larger model's responses so that it learns to handle a specific category of those queries effectively.
The process generally involves
- A large teacher model processes training examples.
- The teacher produces predictions or probability scores.
- A smaller student model processes the same examples.
- The student learns to produce outputs similar to the teacher.
- The student is further evaluated or fine-tuned for its target task.
The goal is to transfer useful knowledge from the larger model into a smaller model, allowing the SLM to retain much of the teacher's task-specific capability with fewer parameters.
2. Quantization
Quantization reduces the amount of memory and computation required by representing a model's numerical values with lower-precision numbers.
During training, neural networks commonly use numerical formats such as 32-bit or 16-bit floating-point values. Quantization can convert these values to lower-precision formats, such as 8-bit or 4-bit representations.
For example, instead of storing a model parameter using a 32-bit value, it may be represented using an 8-bit value. This significantly reduces the memory required to store the model and can make inference more efficient on compatible hardware.
A simplified process looks like this
Higher-precision weights → Lower-precision representation → Smaller memory footprint → More efficient inference
Quantization can be performed after training (post-training quantization) or incorporated into the training process (quantization-aware training).
The main challenge is maintaining model quality. If the precision is reduced too aggressively, the model may lose some accuracy or language-generation quality. Therefore, quantization usually involves finding a balance between model size, inference efficiency, and performance.
3. Pruning
Pruning reduces the size of a model by identifying and removing parameters or connections that contribute relatively little to its output.
Large neural networks often contain parameters that have a limited effect on particular tasks. Pruning techniques attempt to remove these less important components while preserving the model's important learned patterns.
For example, if certain connections contribute very little to a model's predictions, they can be removed or set to zero. The resulting model contains fewer active parameters and may require fewer computational resources.
Pruning can take different forms
- Individual weights can be removed based on their importance, reducing the number of parameters the model needs to process.
- Larger structures, such as neurons, channels, or entire layers, can be removed to reduce the model's overall computational requirements.
- Parameters with smaller numerical values can be targeted for removal, as they often have less influence on the model's output.
After pruning, the model may be fine-tuned to recover some of the performance lost during the removal process.
How These Techniques Work Together
Distillation, quantization, and pruning address different aspects of model efficiency and can be used individually or together.
A typical SLM development process might begin with a larger model, use distillation to create a smaller architecture, apply pruning to remove unnecessary parameters, and then use quantization to reduce the numerical precision of the remaining parameters.
The result is a model that can be smaller, faster, and less resource-intensive, while still retaining the capabilities required for its intended application. The trade-off is that aggressive compression can reduce accuracy, reasoning ability, or generalisation, so these techniques need to be applied according to the model's intended use.
How Are SLMs Trained and Fine-Tuned?
Training a Small Language Model involves teaching it to understand language patterns, generate relevant responses, and perform specific tasks. Depending on how the model is developed, training may involve pre-training a model from scratch or adapting an existing model using techniques such as fine-tuning, instruction tuning, and knowledge distillation.
The overall process can be divided into several stages:
1. Data Collection and Preparation
The first step is preparing the data that the model will learn from. This can include books, websites, documents, code, conversations, domain-specific datasets, and other text sources, depending on the intended use of the model.
The data is cleaned to remove duplicate, irrelevant, low-quality, or potentially harmful content. It is then formatted and processed into a form that can be used during training. For specialised SLMs, the training data may focus heavily on a particular industry, task, language, or type of content.
2. Pre-Training
During pre-training, the model learns general patterns in language by processing large amounts of text. For many transformer-based language models, this involves predicting the next token based on the tokens that came before it.
For example:
Input: The customer requested a refund because the product was
Model prediction: damaged.
By repeating this process across a large dataset, the model learns relationships between words, syntax, context, and broader language patterns.
SLMs generally use smaller architectures and training datasets than large models, allowing them to require fewer computational resources while focusing on the capabilities needed for their intended applications.
3. Knowledge Distillation
Knowledge distillation can be used to create a smaller model from a larger, more capable teacher model. The teacher model produces predictions or other learning signals, and the smaller student model learns to reproduce useful aspects of that behaviour.
This allows developers to transfer selected capabilities from a larger model into a more compact model without requiring the SLM to learn everything from scratch.
For example, a general-purpose LLM could act as the teacher while an SLM is trained to perform a specific task, such as customer-query classification or document summarisation.
4. Supervised Fine-Tuning
After pre-training, an SLM can be fine-tuned using a smaller, task-specific dataset. This dataset contains examples that demonstrate how the model should respond to particular inputs.
For example:
Input: “I can't log into my account.”
Expected output: “Account access issue”
By training on many such examples, the model becomes better at performing the intended task.
Fine-tuning is particularly useful when an SLM needs to work with specific terminology, formats, workflows, or domain requirements.
5. Instruction Tuning
Instruction tuning teaches the model to follow natural-language instructions more effectively. Instead of simply learning language patterns, the model is trained on examples containing an instruction, an input, and an appropriate response.
For example:
Instruction: Summarise the following paragraph in two sentences.
Input: [Text]
Response: [Summary]
This helps the SLM understand what users are asking it to do and produce responses in the expected format.
6. Domain-Specific Fine-Tuning
An SLM can be further fine-tuned using data from a specific domain, such as finance, healthcare, retail, legal services, or customer support.
Domain-specific training helps the model become familiar with industry terminology, common document formats, workflows, and task requirements. This can make a smaller model more effective for specialised applications without requiring the broad capabilities of a general-purpose LLM.
7. Evaluation and Testing
Once training and fine-tuning are complete, the model needs to be evaluated against a separate validation or test dataset.
Evaluation can measure factors such as:
- Accuracy
- Task performance
- Response quality
- Latency
- Memory usage
- Hallucination rate
- Resource consumption
Testing should ideally use data that reflects the model's actual production environment. A model that performs well on general benchmarks may still perform poorly on a specific business task.
8. Optimisation and Deployment
After evaluation, the model can be optimised for its target environment. Techniques such as quantization and pruning can reduce its memory and computational requirements, while further fine-tuning may improve performance on specific tasks.
The final SLM can then be deployed on cloud infrastructure, private servers, local machines, or supported edge devices depending on the application's requirements.
In Simple Terms
The development of an SLM typically follows a cycle of data preparation → pre-training → fine-tuning → evaluation → optimisation → deployment. The exact process varies depending on whether the model is built from scratch, distilled from a larger model, or adapted from an existing pre-trained model.
The goal is not simply to make the model smaller, but to retain the capabilities needed for a specific application while reducing unnecessary computational requirements.
Benefits and Limitations of Small Language Models (SLMs)
Small Language Models offer a practical approach to deploying language-based AI where speed, cost, resource usage, and deployment flexibility are important. Their smaller size can make them easier to operate and specialise for specific tasks, but these advantages come with trade-offs in areas such as reasoning ability, general knowledge, and overall model performance.
Overall, Small Language Models provide a practical balance between AI capability and resource efficiency. Their lower computing requirements, faster inference, reduced costs, and suitability for specialised tasks make them useful for applications where a large language model may be unnecessary. However, their smaller size can limit performance on complex reasoning, broad knowledge, and open-ended tasks. The choice between an SLM and a larger model therefore depends on the application's requirements, available infrastructure, desired accuracy, and level of complexity.
SLM vs LLM vs Hybrid Approach
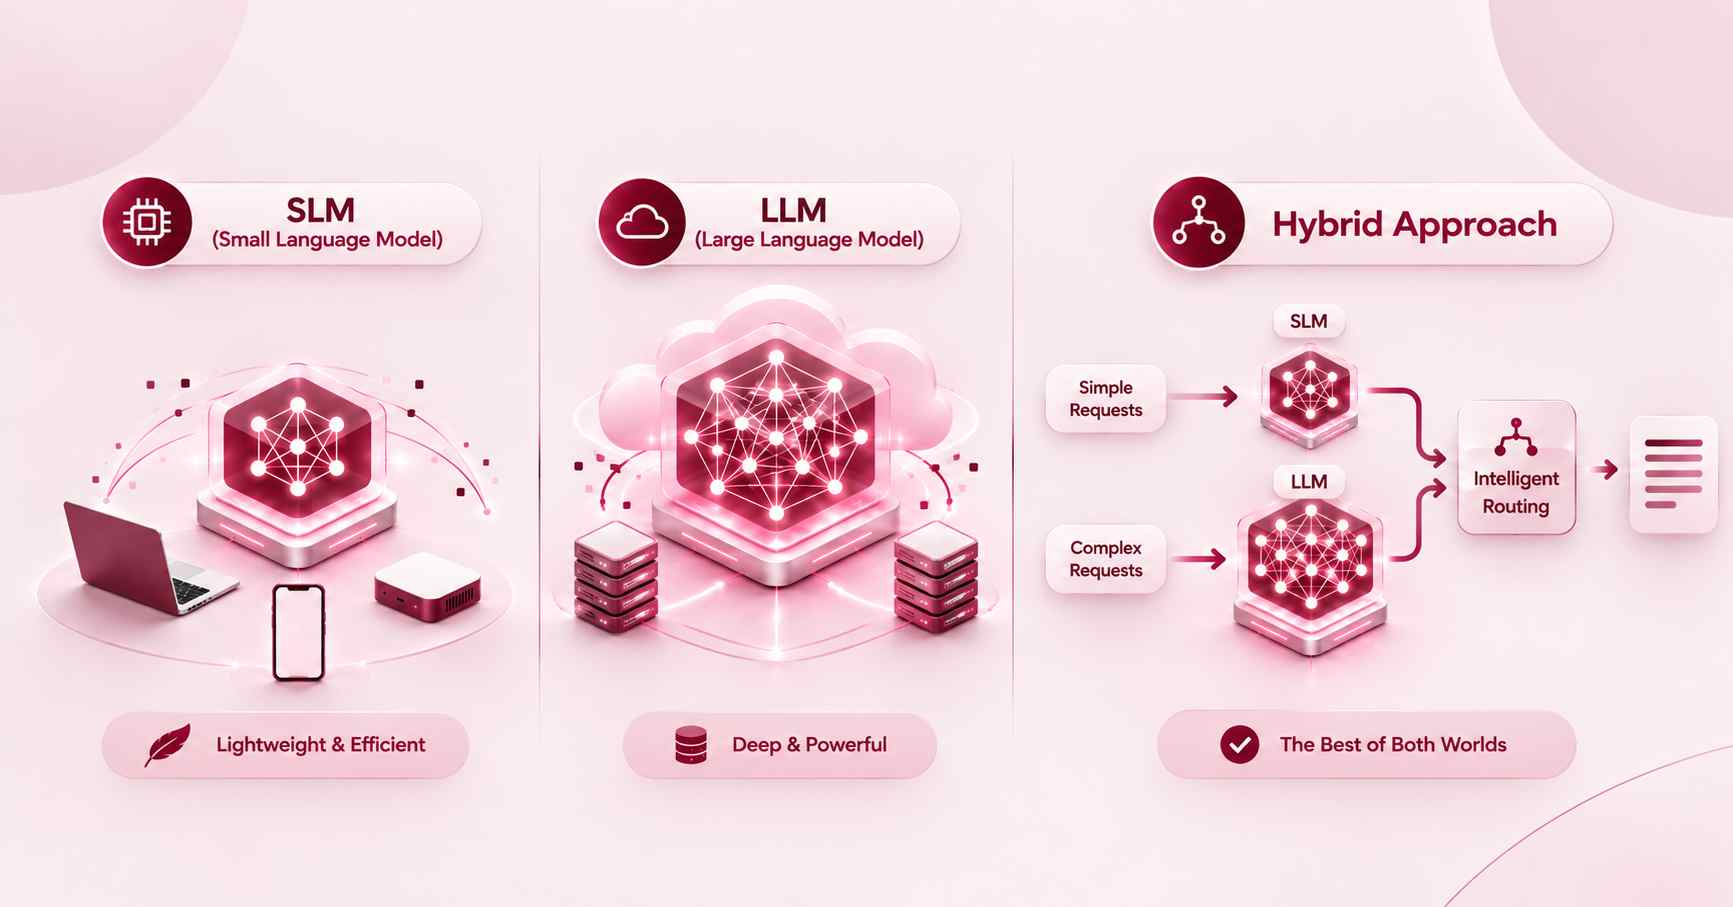
The choice between a Small Language Model (SLM), Large Language Model (LLM), and a hybrid approach depends on the application's requirements, task complexity, computing resources, latency, and cost.
SLM
Small Language Models are compact models designed to handle specific and well-defined AI tasks without requiring the computational resources typically associated with larger models. Their smaller size makes them suitable for applications where faster inference, lower resource consumption, and more controlled deployment are important.
SLMs work well for tasks such as text classification, intent detection, information extraction, summarisation, content moderation, and other domain-specific workloads. They can also be deployed closer to where data is generated, including local infrastructure and edge devices.
Choose an SLM when:
- The application has a focused or predictable workload.
- Low latency is important.
- Computing resources are limited.
- Data needs to remain within a local or controlled environment.
- Keeping inference costs lower is a priority.
LLM
Large Language Models are designed to handle a much broader range of language tasks and can work with complex instructions, diverse queries, and multi-step reasoning requirements. Their larger capacity allows them to generate detailed content, understand context across longer interactions, and handle tasks that may be difficult for smaller specialised models.
LLMs are particularly useful when an application needs broad language understanding, advanced content generation, complex reasoning, or the ability to handle unpredictable user requests.
Choose an LLM when:
- The application involves complex reasoning.
- Users can ask a wide variety of questions.
- Advanced text generation is required.
- The task requires broader knowledge and contextual understanding.
- The application involves multiple or complex steps.
Hybrid Approach
A hybrid approach combines SLMs and LLMs within the same AI architecture, allowing each model to handle the type of work it is better suited for. Instead of sending every request to a large model, the system can use an SLM for simpler tasks and route more complex requests to an LLM.
For example, an SLM could first classify a user's request. If the request is a simple FAQ or classification task, the SLM can handle it directly. If it requires deeper reasoning or a detailed response, the system can pass it to an LLM.
This approach can help organisations balance performance, cost, speed, and model capability across different parts of an application.
Choose a hybrid approach when:
- The application handles both simple and complex workloads.
- Different tasks require different levels of model capability.
- You want to limit unnecessary LLM usage.
- The system needs both fast responses and advanced reasoning.
- You want to distribute workloads between local and cloud-based models.
Which One Should You Choose?
The decision ultimately depends on the nature of the workload. SLMs are better suited to focused and resource-conscious applications, LLMs are better for complex and broad language tasks, while hybrid architectures are useful when an application needs both. In many enterprise applications, a hybrid setup can allow smaller models to handle routine operations while larger models are reserved for tasks that genuinely require their additional capabilities.
Use Cases of Small Language Models (SLMs)
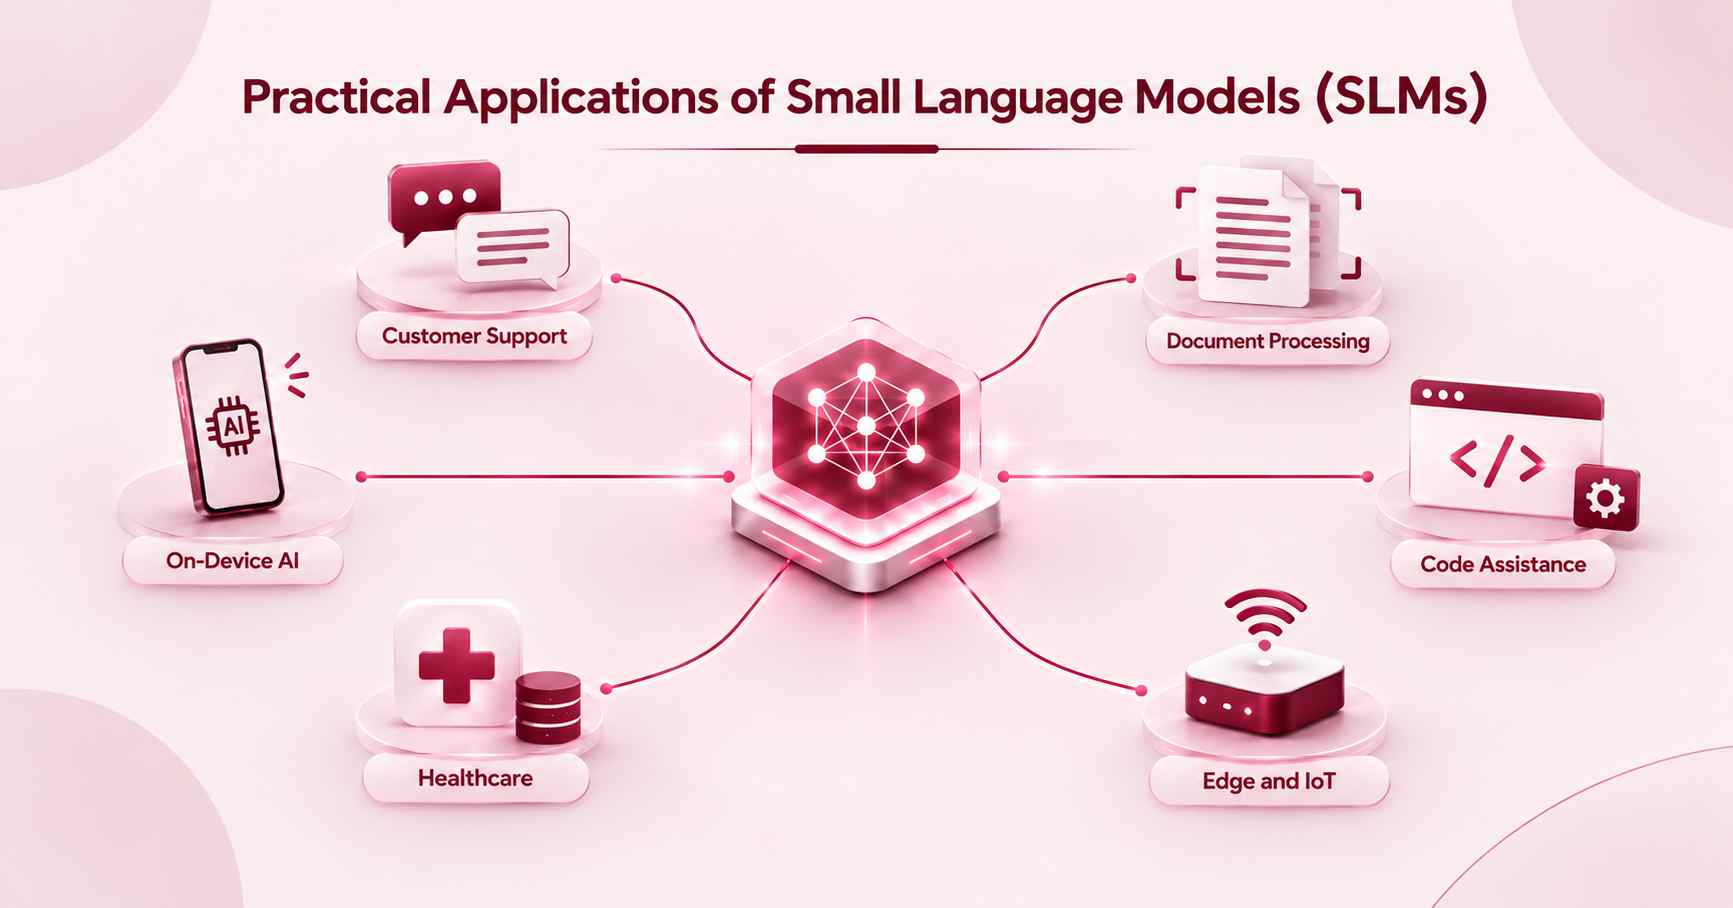
Small Language Models are well suited to applications that involve focused, repetitive, or domain-specific language tasks. Their smaller size allows organisations to integrate language capabilities into applications without requiring the infrastructure typically needed to run larger models. They are particularly useful when an application prioritises faster responses, lower resource consumption, local processing, or predictable performance.
1. Customer Support
SLMs can be used to power customer-support chatbots that answer frequently asked questions, understand customer intent, and route queries to the appropriate department. Since many support systems operate within a defined set of topics, a smaller model can be trained or fine-tuned to handle these interactions effectively.
They can also assist support teams by summarising conversations, identifying recurring issues, and suggesting responses to common queries. Running an SLM for these focused tasks can help reduce processing requirements while maintaining quick response times for customers.
2. Text Classification
SLMs can process large amounts of text and assign it to predefined categories based on its topic, intent, sentiment, or purpose. This makes them useful for sorting emails, support tickets, feedback, reviews, and other forms of unstructured text.
For example, an organisation can use an SLM to identify whether an incoming support request relates to billing, account access, technical problems, or general enquiries. Because the classification task has clearly defined categories, a smaller model can often handle it efficiently.
3. Document Processing
SLMs can help organisations process large collections of documents by extracting relevant information, identifying important sections, and generating concise summaries. They can work with documents such as reports, forms, invoices, internal records, and business correspondence.
They can also convert information from unstructured text into structured formats that can be used by other software systems. This reduces the amount of manual work required for repetitive document-related tasks, particularly when the model is specialised for a particular type of document.
4. On-Device AI
SLMs can be deployed directly on devices such as smartphones, laptops, tablets, and other computing devices. Instead of sending every request to a remote server, the device can perform certain language-processing tasks locally, provided the hardware has sufficient resources.
This approach can be useful for features such as text suggestions, voice-command interpretation, note summarisation, and offline assistants. Local processing can also reduce dependence on network connectivity and may improve response times for simple tasks.
5. Personal Assistants
SLMs can support personal-assistant applications that perform focused tasks such as understanding commands, summarising notes, generating reminders, or organising information. Their smaller resource requirements make them suitable for assistants that do not need the broad reasoning capabilities of a large language model.
For example, an assistant running on a local device could interpret commands such as creating a reminder, summarising a note, or finding information within locally stored content. The model can be specifically optimised for the limited set of tasks the assistant needs to perform.
6. Content Summarisation
SLMs can summarise emails, meeting notes, reports, support conversations, and other text-heavy content. They can identify the main points and produce shorter versions that are easier to review, particularly when the summarisation requirements are consistent.
This makes them useful for organisations that need to process large volumes of similar content. A model fine-tuned for a specific type of document can focus on the information that matters most rather than requiring the broader capabilities of a general-purpose model.
7. Code Assistance
SLMs can be used for focused software-development tasks such as code completion, code explanation, documentation generation, and basic error identification. Smaller coding models can be integrated into development environments where quick responses are important.
They can also be deployed locally to assist developers without sending source code to an external service. However, their usefulness depends on the programming languages, frameworks, and complexity of the development tasks they have been trained to handle.
8. Industry-Specific Applications
SLMs can be fine-tuned for specific industries by training them on relevant terminology, documents, workflows, and task requirements. This can make them useful in areas such as finance, healthcare, retail, manufacturing, and legal operations.
Instead of requiring the model to understand every possible topic, organisations can focus its capabilities on a narrower domain. This can improve its effectiveness for specialised tasks while keeping the model smaller and easier to deploy.
9. Edge and IoT Applications
SLMs can bring language-processing capabilities to edge devices and Internet of Things (IoT) systems where computing resources, network connectivity, or bandwidth may be limited. A compact model can process certain inputs locally instead of continuously communicating with a cloud-based AI system.
For example, an industrial device could use an SLM to interpret a limited set of natural-language commands, classify operational messages, or identify specific instructions. This can make language-based interaction possible even in environments where constant cloud connectivity is impractical.
10. Privacy-Sensitive Applications
SLMs can be deployed on private infrastructure or directly on devices to process information without necessarily sending the data to an external AI provider. This can be useful for organisations handling confidential documents, internal communications, or proprietary information.
Local or private deployment does not automatically guarantee privacy, since security still depends on how the complete system is designed and managed. However, keeping processing within controlled infrastructure can give organisations greater control over how sensitive information is handled.
Popular Small Language Models
Several small language models are available today, with different strengths in reasoning, multilingual tasks, coding, local deployment, and edge applications. The right choice depends on the model size, task requirements, hardware, context length, licensing, and whether the model needs to run locally or in the cloud.
1. Qwen3
Qwen3 is a family of open-weight models from Alibaba's Qwen team. Its smaller dense models include Qwen3-0.6B, Qwen3-1.7B, Qwen3-4B, and Qwen3-8B, making the family suitable for different hardware and workload requirements. Qwen3 supports tasks such as reasoning, coding, instruction following, and multilingual text processing.
The smaller Qwen3 variants are useful when developers need a model that can run locally while still handling more than simple classification or extraction tasks. Qwen3-4B is particularly relevant for applications that need a balance between model capability and resource requirements.
2. Gemma 3
Gemma 3 is Google's family of lightweight open models. The family includes models ranging from 270M and 1B parameters to 4B, 12B, and 27B, with the smaller variants aimed at resource-constrained environments. The 4B model can process both text and images, while the 270M and 1B versions are designed for environments such as mobile devices and single-board computers.
Gemma 3 can be used for tasks such as summarisation, question answering, document processing, and AI assistants. Its smaller variants are especially useful when deployment hardware has limited memory or compute capacity.
3. Phi-4-mini
Phi-4-mini is Microsoft's compact model with around 3.8 billion parameters. It is designed for environments where memory, compute, or response time can be limiting factors, while still providing capabilities for reasoning and instruction following. The model supports a 128K-token context length and is available under the MIT license.
Phi-4-mini can be used for AI assistants, reasoning-focused applications, document-based tasks, and other applications where a larger model may be unnecessary. Microsoft also provides support for local and server-based deployment through tools such as Transformers, vLLM, and Docker.
4. Llama 3.2
Meta's Llama 3.2 family includes smaller 1B and 3B text models. These models are widely used for local AI applications because their smaller size makes them easier to run on devices with limited resources compared with larger Llama models.
Llama 3.2 can be used for conversational applications, text generation, summarisation, classification, and other language-based tasks. Its broad ecosystem also makes it a practical option for developers who want access to existing tools, libraries, and deployment frameworks.
5. Ministral 3
Mistral's Ministral 3 family includes small dense models in 3B, 8B, and 14B sizes. Mistral describes these models as being designed for efficient deployment, including local and edge use cases. The family is available under the Apache 2.0 license.
The smaller Ministral models can be considered for applications such as local assistants, analytics, agentic workflows, and other workloads where running inference closer to the device is useful. Earlier Ministral models were also specifically positioned for on-device and edge computing, including local translation and internet-independent assistants.
Choosing Between Popular SLMs
There is no single best SLM for every application. A 1B model may be enough for classification or simple extraction, while a 3B–8B model may be more appropriate for generation, reasoning, coding, or RAG applications.
When comparing models, consider:
- Model size: Smaller models generally require less memory and compute.
- Task performance: Test the model on the actual workload rather than relying only on general benchmarks.
- Context length: Check how much text the model can process in a single request.
- Hardware: Make sure the model fits the available CPU, GPU, RAM, or edge device.
- Language support: Important for multilingual applications.
- License: Check whether the license fits the intended commercial or research use.
- Fine-tuning: Consider whether the model can be adapted to your domain or task.
- Deployment: Check support for local, edge, private-cloud, or standard cloud environments.
The most suitable SLM is therefore the one that meets the application's accuracy and capability requirements without using more compute, memory, or infrastructure than necessary.
How to Choose an SLM
Choosing the right Small Language Model depends on the task, model performance, deployment environment, resource availability, and business requirements. A smaller model is not automatically the better choice; the goal is to find a model that provides the required performance without unnecessary computational overhead.
In short, choosing an SLM is about finding the right balance between performance and efficiency. Consider the task it needs to perform, the resources available, where it will be deployed, and the required level of accuracy, privacy, speed, and cost before making a decision.

Frequently Asked Questions

Conclusion
Small Language Models offer a practical way to build AI applications without always relying on large, resource-intensive models. Their smaller size can reduce memory and compute requirements, improve response speed, lower inference costs, and make local or edge deployment more practical.
However, SLMs are not a replacement for LLMs in every situation. They may be better suited to focused tasks such as classification, extraction, summarisation, intent detection, and domain-specific assistants, while larger models can be more suitable for complex reasoning, broad knowledge, and open-ended tasks. A hybrid approach can combine both, using an SLM for simpler workloads and an LLM when greater capability is needed.
Choosing an SLM ultimately depends on the task, required accuracy, available hardware, context length, deployment environment, privacy requirements, and cost. As smaller models continue to improve, they are becoming a practical option for businesses looking to build efficient, specialised, and locally deployable AI applications.
 WhatsApp
 Call Us
 Mail Us